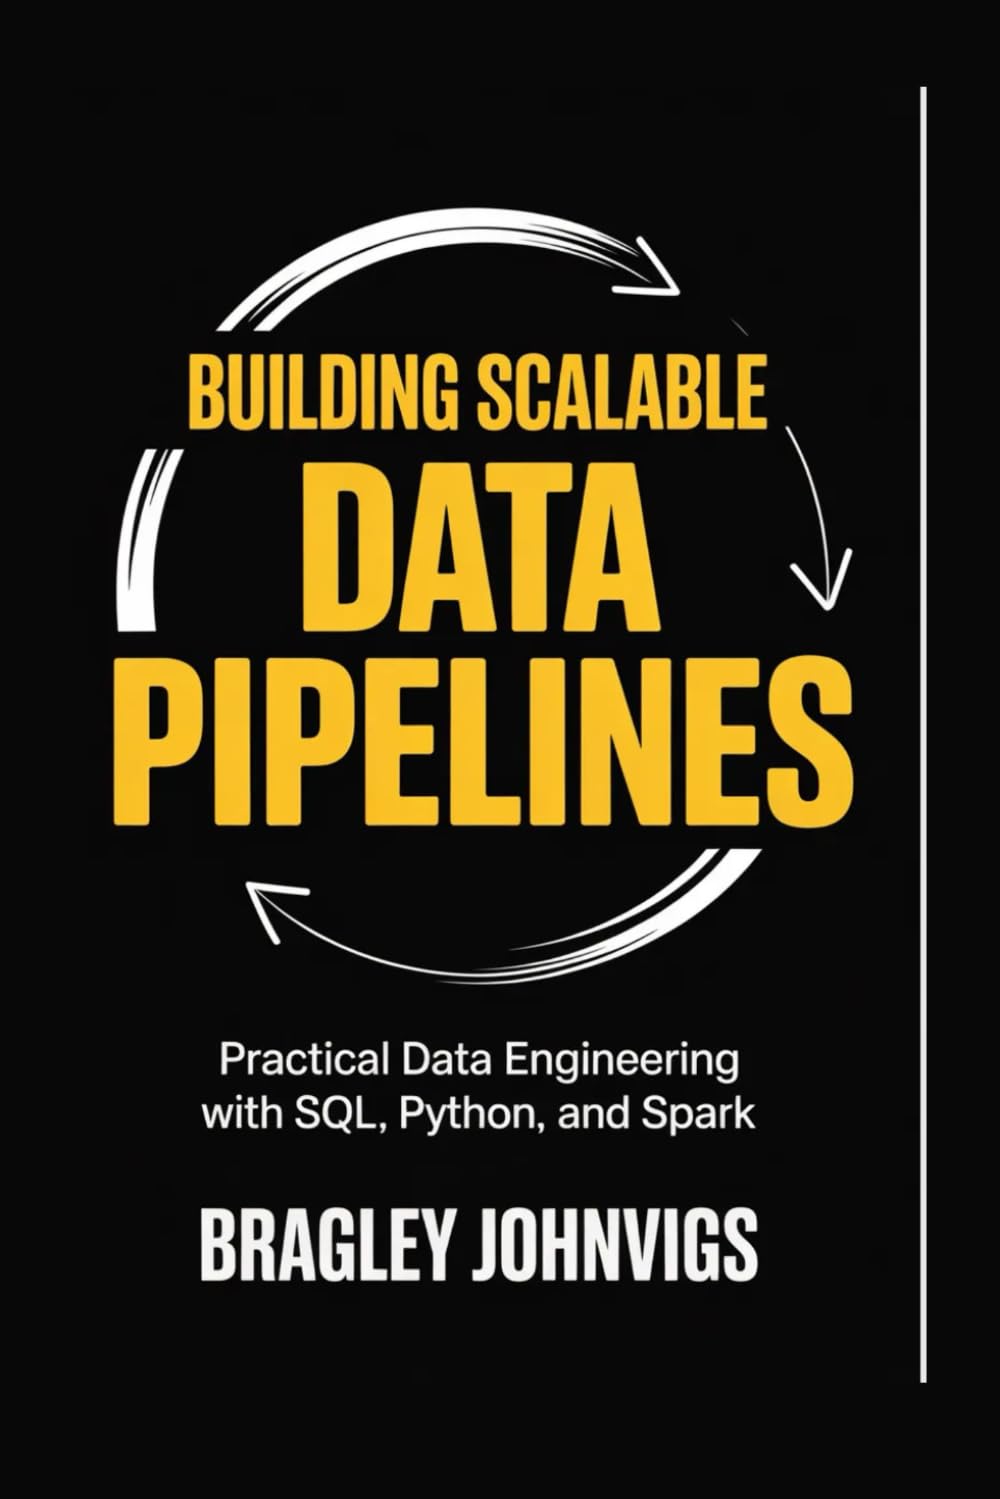
ler totalmente Building Scalable Data Pipelines: Practical Data Engineering with SQL, Python, and Spark
por Bragley Johnvigs
Building Scalable Data Pipelines: Practical Data Engineering with SQL, Python, and Spark
In today's data-driven world, mastering core data engineering skills is essential for anyone looking to thrive in tech, analytics, or AI roles. "Core Data Engineering Skills: Building Data Pipelines with SQL, Python, and Spark" is your ultimate guide to constructing robust, scalable data pipelines that power business decisions and innovation. Whether you're a beginner transitioning from software development or an experienced engineer seeking to refine your toolkit, this book delivers practical, hands-on knowledge to transform raw data into actionable insights. Start with the fundamentals: Dive into SQL for querying and manipulating datasets, Python for scripting and automation, and Apache Spark for handling massive-scale processing. You'll learn to set up environments, build ETL processes, and orchestrate workflows that handle batch and streaming data seamlessly. Key chapters explore advanced techniques like SQL optimization, Python libraries (Pandas, NumPy), Spark DataFrames, and real-time streaming with Kafka integration-ensuring you can tackle complex challenges like data quality, security, and cloud scaling on platforms like AWS or GCP. What sets this book apart? It's packed with real-world case studies, such as building e-commerce recommendation pipelines or IoT data systems, drawing from top bestsellers like "Fundamentals of Data Engineering" and "Designing Data-Intensive Applications." These examples address common gaps, like troubleshooting errors or optimizing for cost, while incorporating review insights for more interactive learning-think checklists, quizzes, and code snippets you can run immediately. No more theory without application; every concept builds progressively, from intro hooks to advanced governance, helping you future-proof your skills against AI trends. By the end, you'll confidently design pipelines that are reliable, efficient, and maintainable, just like the systems powering companies like Google or Netflix. This isn't just a book-it's a career accelerator. Don't miss out on unlocking your potential in data engineering. Grab your copy now and start building the pipelines that drive tomorrow's success!
Procurando Building Scalable Data Pipelines: Practical Data Engineering with SQL, Python, and Spark? Aqui você encontra tudo sobre este livro de Bragley Johnvigs em 20 de fevereiro de 2026. Nesta página estão a descrição da obra, os detalhes da edição (354 páginas) e os formatos disponíveis para baixar: pdf, epub, txt, djvu. Se você gosta de Livros Internacionais, Computação, Informática e Mídias Digitais, Base de Dados, SQL, explore também outros títulos da mesma categoria no Encontrando os melhores livros. Veja ainda as outras obras de Bragley Johnvigs em nosso catálogo.
Autores populares
Icon Group International (283) Publishing lmgdaw (250) Nikolay Krechet (145) Kennie B Journals (120) Charles Nehme (106) Riddler Books (105) webmarbook design (103) Mint and Cherry Notebooks (82) Jillo Trukudo (80) Ondrej Sarek (76) Iwona Makara (74) Just Visualize It (71) Moonpeak Library (69) Quick Witted Coconut (69) Mary Hirose (67) Talor Press (67) Various (67) Marina Buchholz B.Eng (58) Miller Sye (58) NAK Legal Publishing (58)Principais publicadores
Independently published Forgotten Books Routledge Taschen Dover Publications Wiley Oxford University Press CRC Press Kessinger Publishing Princeton University Press Cambridge University Press Springer Bloomsbury Academic O'Reilly Media Hal Leonard Publishing Corporation Tuttle Publishing Rizzoli International Publications Content provided by MemoryLane.com Editorial Tirant lo Blanch Thames & Hudson